Skip to content

Data annotation & data labeling company

Ground truth,
engineered.

Nex Annotation, a NexTribes company, is a managed labelling team for computer vision, medical imaging, language and speech. Written guidelines, trained annotators and a measured QA loop, so your model learns from data you can defend.

  • 3-layer QA on every task
  • Metrics in every delivery
  • Your tool or ours

See the work,
not a stock photo.

Real frames from a production project our team captured, labelled and reviewed: 23,551 railway frames from five Indian routes, every box checked by hand.

Case study · Rail infrastructure

Railway overhead-line detection

Cabin-camera video from five Indian routes, labelled so a pantograph’s height can be measured straight from a detection. Every frame was proposed by a model, then corrected and reviewed by hand.
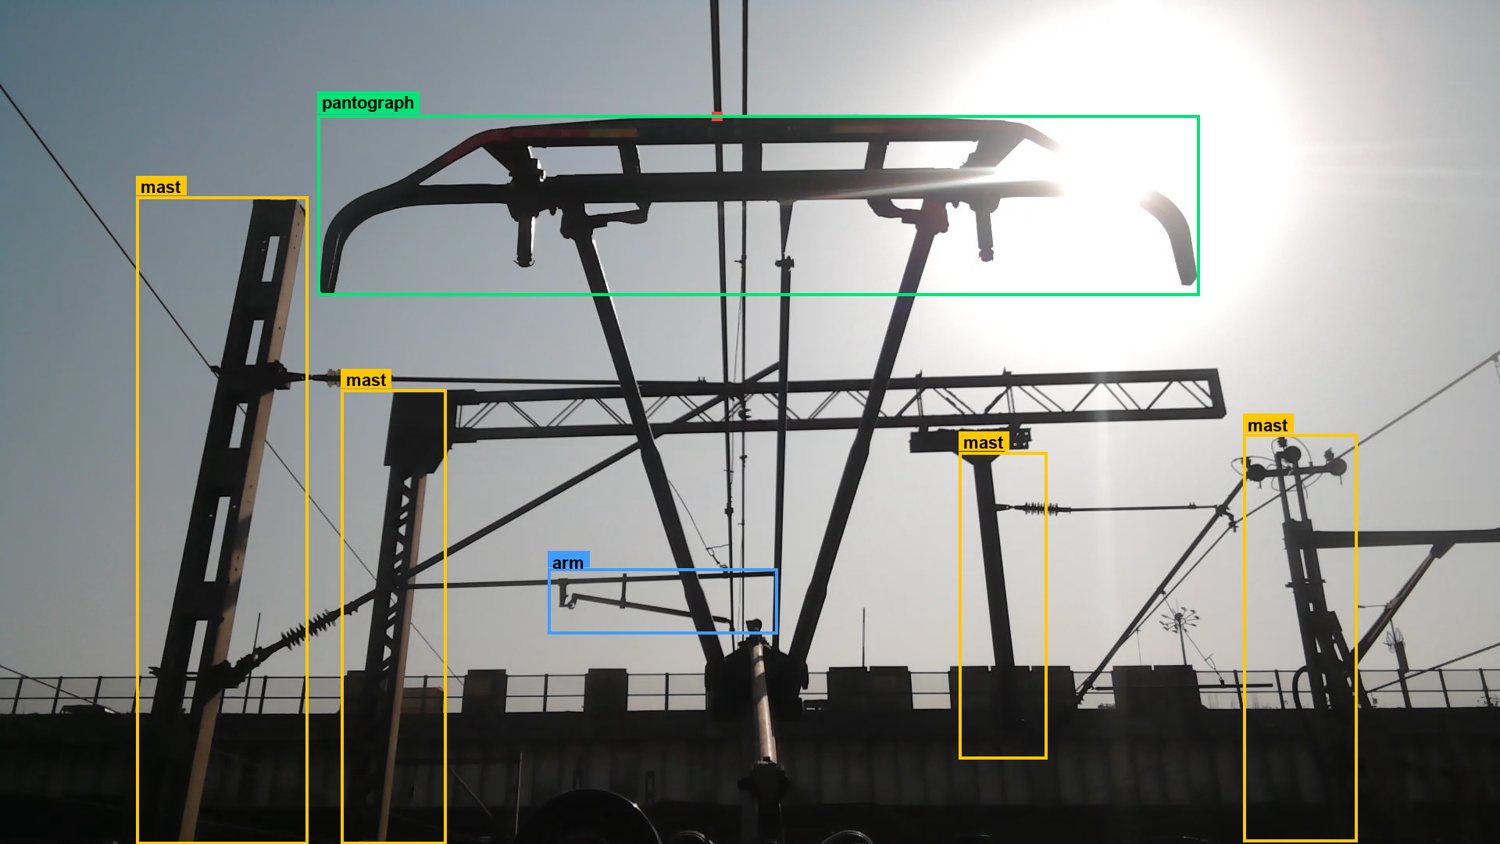
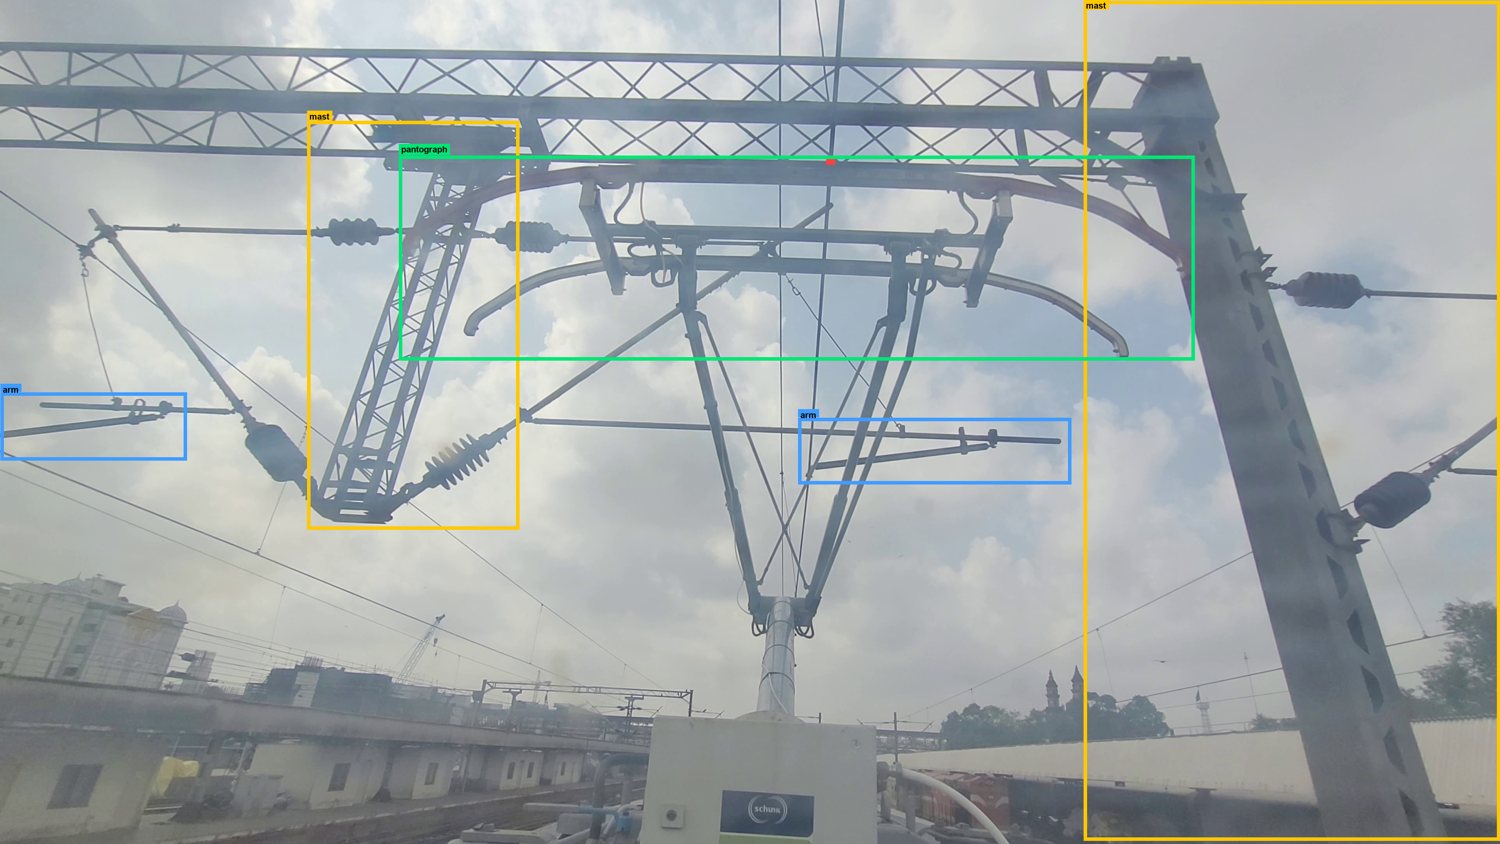
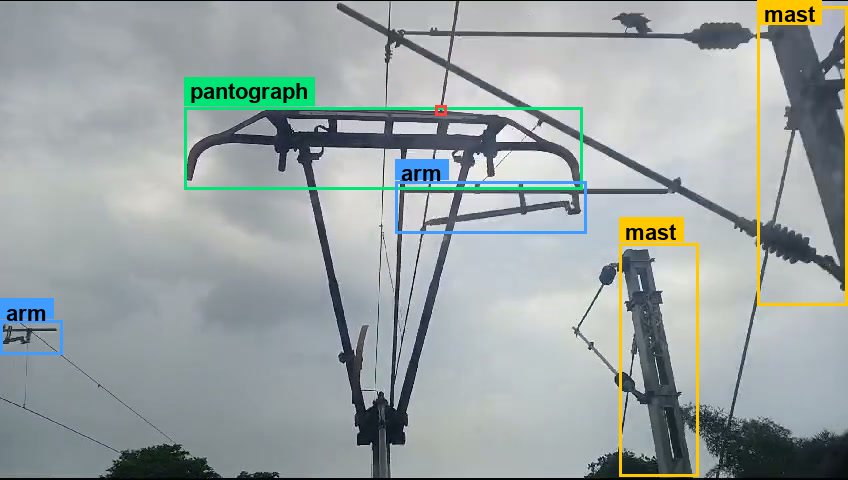
Labelled railway frame, Mumbai: 14 boxes in one frame: masts, arms and the pantograph against direct sun.

Mumbai14 boxes in one frame: masts, arms and the pantograph against direct sun.

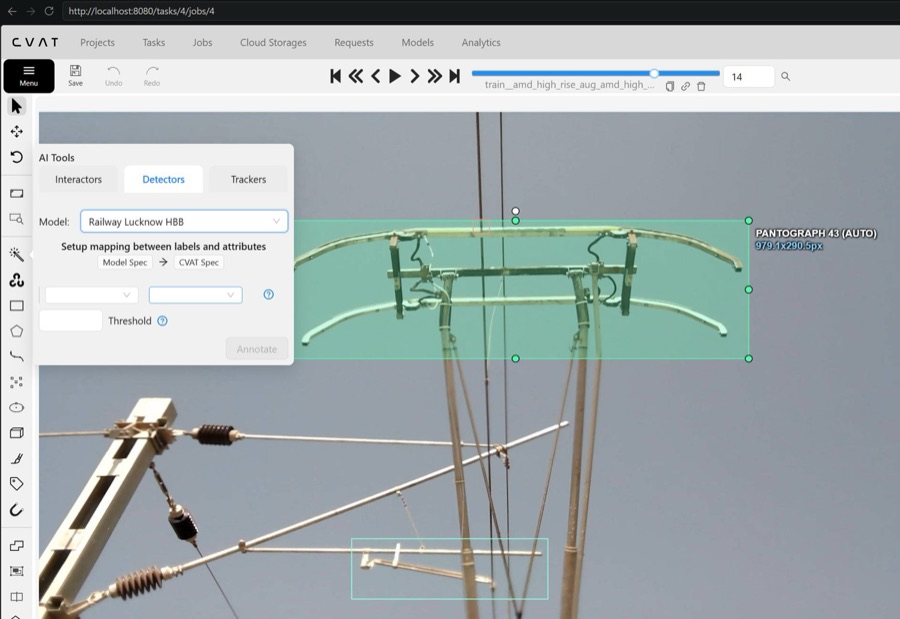
  1. Proposal: A pretrained detector proposes boxes inside CVAT.

    01Proposal

    A pretrained detector proposes boxes inside CVAT.

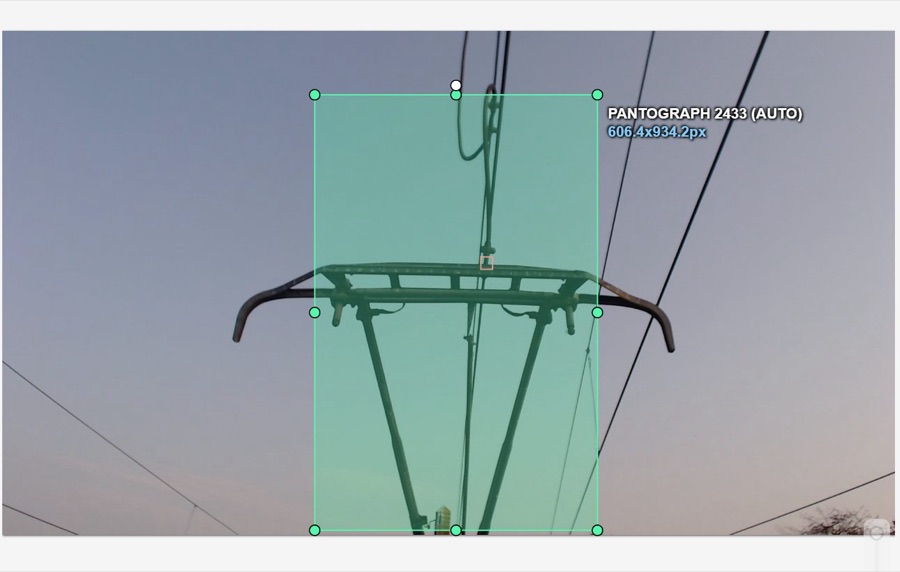
  2. Correction: A proposal that runs too tall is caught by the labeller.

    02Correction

    A proposal that runs too tall is caught by the labeller.

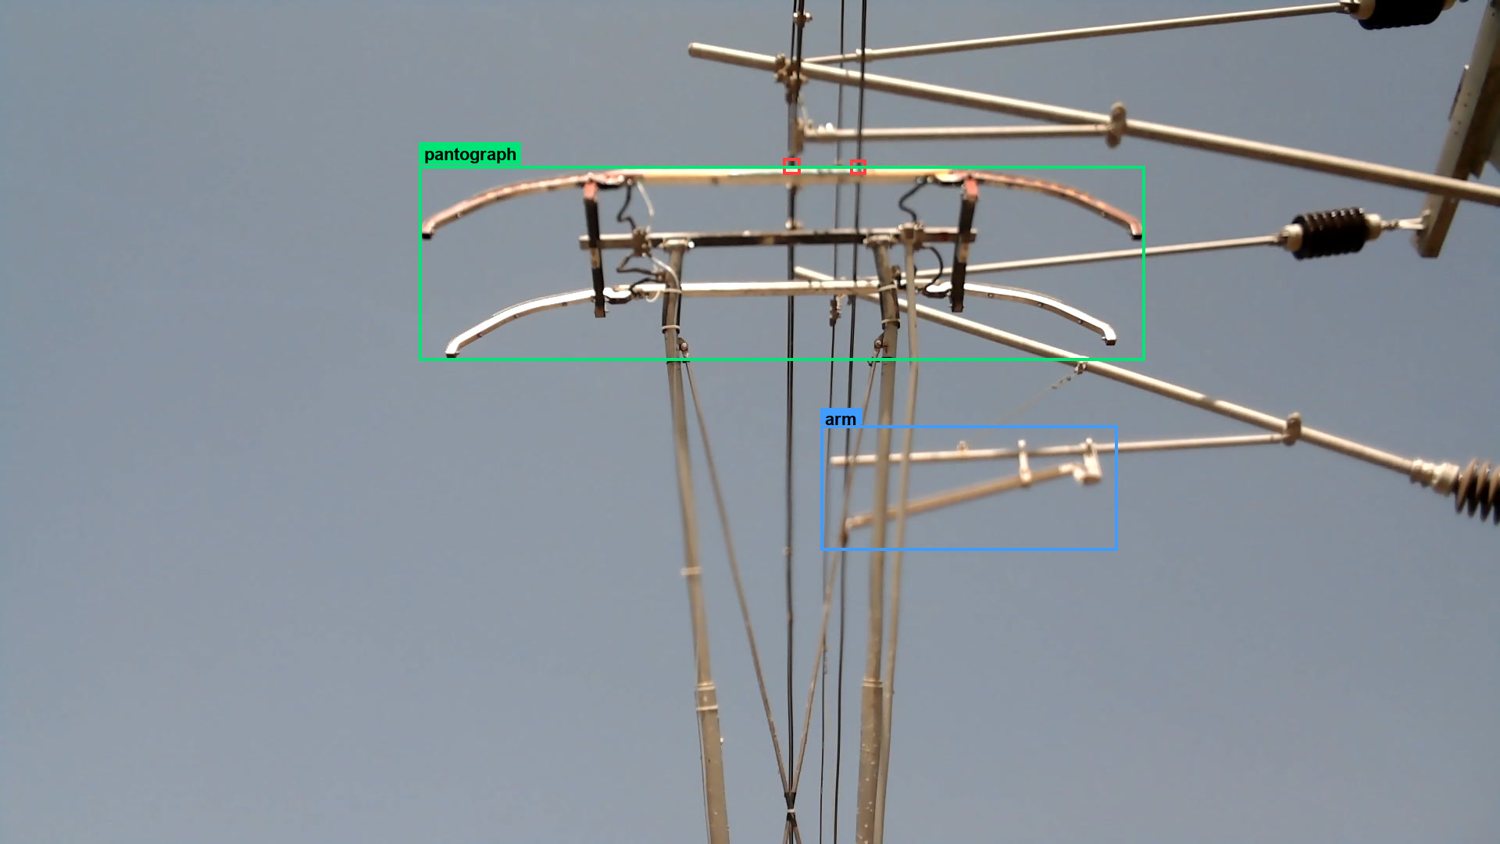
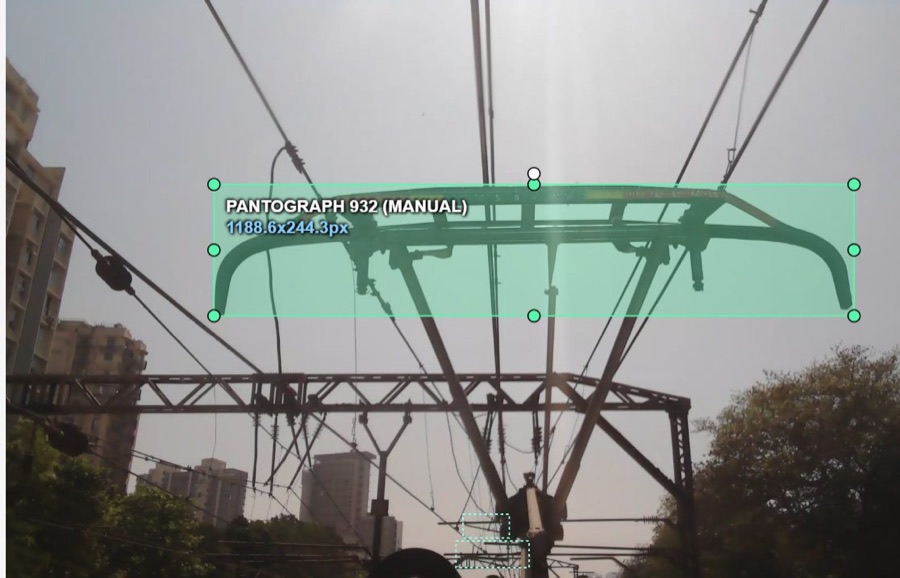
  3. Review: The fixed box after a second-pass reviewer signs it off.

    03Review

    The fixed box after a second-pass reviewer signs it off.

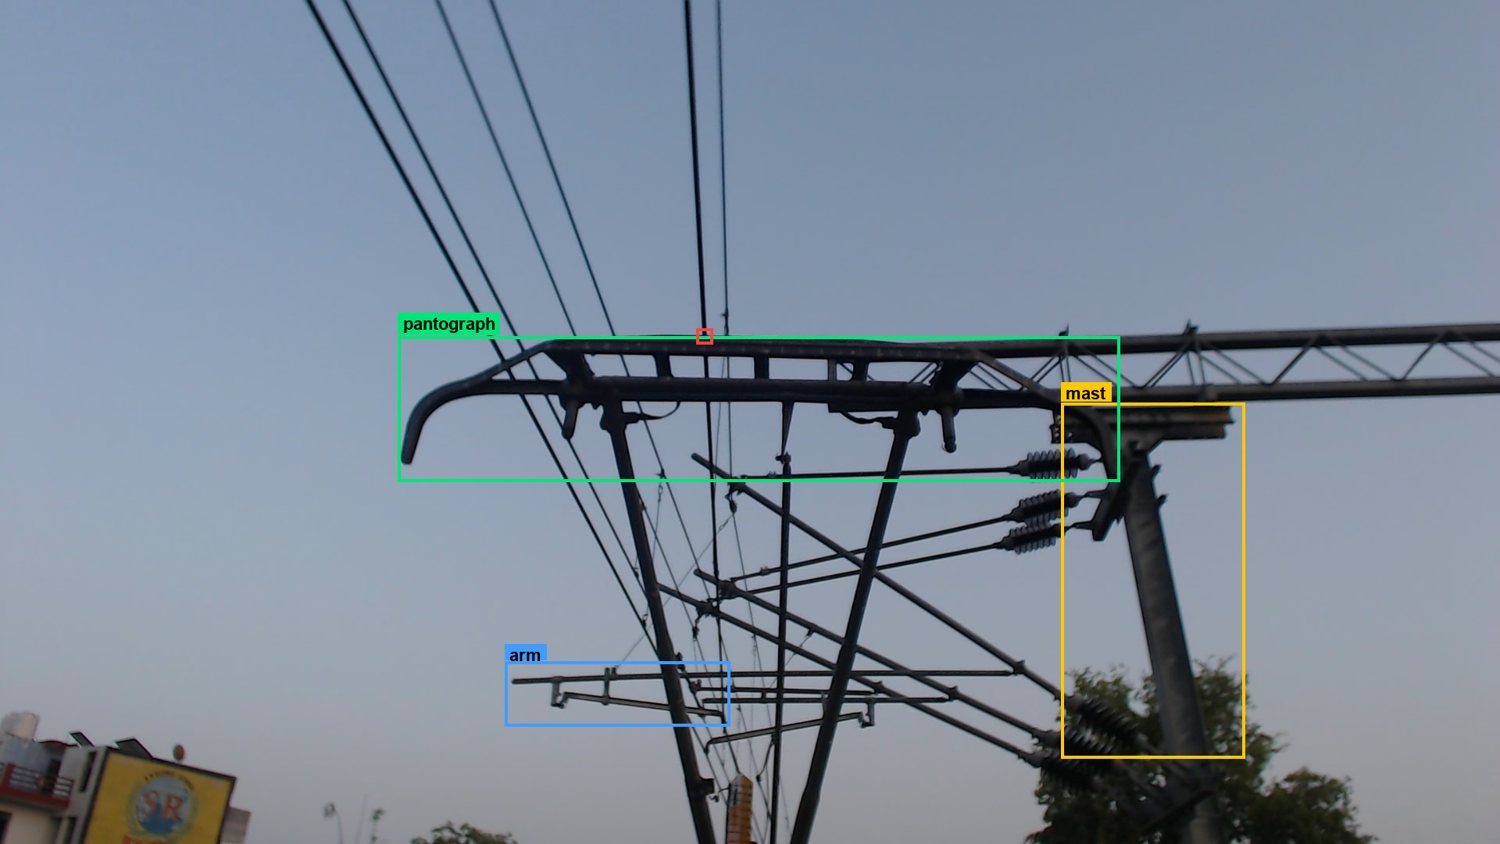
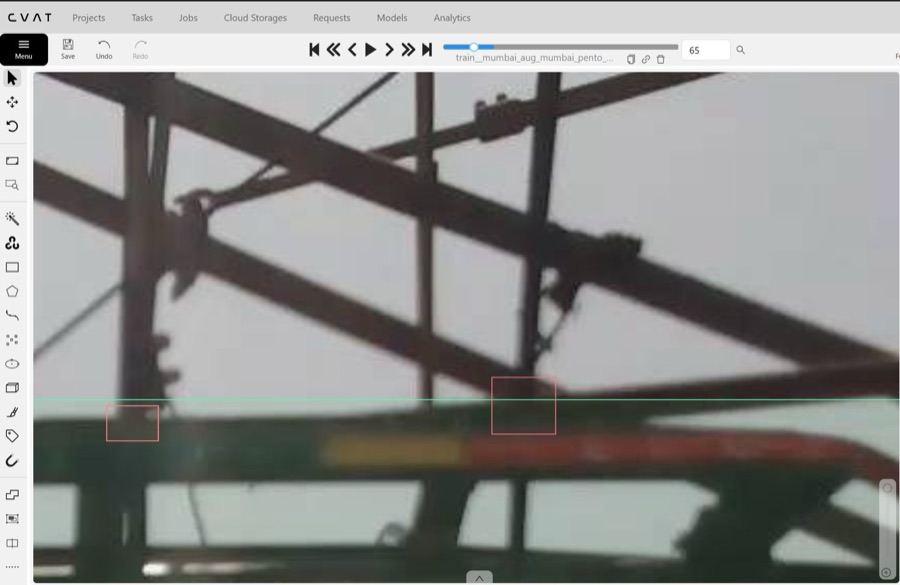
  4. Hardest class: Contact points are ~1% of frame width, placed at high zoom.

    04Hardest class

    Contact points are ~1% of frame width, placed at high zoom.

Real project frames from our public showcase (CC BY-NC-SA 4.0). The full 8 GB dataset stays private · View on Kaggle ↗

Working inside

CVATLabel StudioLabelboxEncordV7 DarwinSuperAnnotateSuperviselyRoboflowSegments.ai3D SlicerKiliCustom toolingCVATLabel StudioLabelboxEncordV7 DarwinSuperAnnotateSuperviselyRoboflowSegments.ai3D SlicerKiliCustom tooling

Why Nex

Most labelling vendors sell hours. We sell agreement: between annotators, with your guideline, and with the metric your model is judged on.

01

Guideline first

Every project starts with a written, versioned guideline that settles edge cases before anyone draws a box. You approve it; we are held to it.

02

Measured, not promised

A blind gold set is scored in every batch. IoU, Dice, kappa or WER, per class, in a report you can forward to your ML lead.

03

Built for your stack

We label inside your platform, export in your schema and adapt to your release cadence. No new tool for your team to learn.

More task types,
drag to compare.

Synthetic demo scenes in the classes, conventions and export formats we deliver to clients: geospatial, agriculture, sports, medical, retail, language and speech.

BUILDING · 72 VEGETATION WATER
Labelled
Raw
‹ ›

Demonstration scenes are synthetic and generated for this site. No client data is shown. Drag the divider to compare.

From first call to
first batch in a week.

A short, documented path from your sample data to a production team, with a fixed-fee pilot before any production commitment.

  1. 01Day 0–2

    Scope

    A working call with your ML lead. We review sample data, the classes you need, edge cases you already know about, volume and timeline.

  2. 02Day 2–4

    Guideline

    We write the labelling guideline. Every class defined, every edge case illustrated with a correct and an incorrect example. You approve it before anyone labels.

  3. 03Day 4–9

    Pilot

    A fixed-fee pilot on a real slice of your data, credited against your first production order. You receive labels and a full QA report, so the decision rests on measured results.

  4. 04Ongoing

    Production

    A dedicated, trained team works in batches. Every task passes three quality layers, and every batch ships with its own report.

  5. 05Every batch

    Feedback loop

    Your model’s errors become our next guideline revision. We track rework, retrain annotators and version every rule change.

The full process and QA model →

Quality

Every batch ships
with its receipts.

Three review layers on every task, a blind gold sample in every batch, and a report that shows exactly where the data is strong and where it isn’t.

  1. L1
    Annotator self-check

    Checklist and automated validation (empty boxes, impossible sizes, swapped keypoints) before submit.

  2. L2
    Peer review

    A second trained annotator reviews 100% of tasks and returns errors with a reason code.

  3. L3
    QA lead audit

    A sampled audit against the gold set. Batches below target are reworked before they reach you.

Batch report

PRJ-ADAS · Batch 14

Accepted

Frames

2,400

Objects

33,033

Mean IoU

0.931

Rework

2.1%

ClassObjectsIoURecallRework
car 18,412 0.947 0.991 1.2%
truck 2,106 0.931 0.986 2.1%
pedestrian 6,930 0.912 0.978 3.4%
cyclist 1,204 0.904 0.972 3.9%
traffic_sign 4,381 0.928 0.989 1.8%
Gold sample 5% · blindGuideline v1.6IAA κ 0.84
Example report · illustrative figures

Domain context
is part of the label.

Annotators are trained per industry, so a radiologist’s “ground-glass opacity” and a retailer’s “facing” mean exactly what you mean.

  • 01

    Autonomous Mobility

    Perception data for cars, shuttles, trucks and delivery robots: camera, LiDAR and fused.

    3D cuboidsLanesSegmentationTracking
  • 02

    Medical & Life Sciences

    Clinician-reviewed labels on de-identified data, under your protocol and access rules.

    DICOM segmentationPathologyClinical NLP
  • 03

    Retail & E-commerce

    Shelf audits, planogram compliance, catalogue enrichment and visual search.

    SKU detectionAttributesProduct cut-outs
  • 04

    Agriculture

    Drone and ground imagery for yield estimation, spraying and plant health.

    Crop / weed boxesField polygonsDisease classes
  • 05

    Geospatial

    Satellite and aerial labelling delivered in GeoJSON with clean topology.

    Building footprintsLand coverChange detection
  • 06

    Sports Analytics

    Athlete skeletons, ball tracking and match events from broadcast and training footage.

    PosePlayer trackingEvent tagging
  • 07

    Manufacturing

    Visual inspection data where the rare defect is the one that matters.

    Defect masksAssembly checksLine video
  • 08

    Security & Smart Cities

    Privacy-conscious labelling for safety, traffic and infrastructure systems.

    Person / vehicle trackingEventsAnonymisation
  • 09

    Generative AI

    Human feedback and evaluation data for language and vision-language models.

    Preference rankingRubric evalsCaptioning

Your data is
not our data.

Security is designed into how the team works, not added as a policy document afterwards.

Access

Named people only

Only annotators assigned to your project can open your data, through role-based accounts with MFA.

Devices

Locked workstations

Managed machines with USB, screenshots and personal devices disabled on the production floor.

Residency

Your cloud, your tool

We can work entirely inside your platform or VPC so files never leave your environment.

Legal

NDA & DPA

We sign your NDA or data-processing agreement before the first file is shared.

Privacy

De-identified by default

Medical and personal data is handled de-identified, under GDPR- and HIPAA-aligned procedures.

Retention

Deleted at close

All working copies are deleted when the project ends, with written confirmation.

Questions

Questions we hear
in scoping calls.

Ask us anything →
01How does the pilot work?

After a scoping call we propose a fixed-fee pilot on a representative sample, typically 500 to 2,000 images, clips or documents. We write the guideline, label the set and return it with a full QA report in about a week. The pilot fee is credited against your first production order, and the production quote is based on the throughput we measured.

02Do you work in our annotation platform?

Yes, and we prefer to. Your data stays in your environment and you see progress in real time. We work in CVAT, Label Studio, Labelbox, Encord, V7, SuperAnnotate, Supervisely and others. If you have no tooling, we host a private CVAT instance for you.

03How do you measure quality?

Against a gold set we build with you during the pilot. Each batch is scored with the metric that matches the task (IoU for boxes, Dice for medical masks, kappa for text, WER for speech) and the numbers are in the report, per class.

04What happens to our data?

It is accessed only by the named people on your project, on managed workstations with no external storage. We sign your NDA or DPA, and delete all copies at the end of the engagement with a written confirmation.

05How fast can you scale?

Projects start with a core team that learns your guideline in depth. We scale by adding annotators who are trained and certified on your gold set first, so growth does not dilute quality.

06How is pricing calculated?

Per object, per asset, per audio hour or per annotator-hour, whichever matches how your task varies. The pilot gives us real throughput numbers, so the quote you get is grounded in your data.

Next step

Scope your project with
an annotation lead.

A 30-minute call with the person who would run your project. We review a sample of your data, recommend an approach and send a fixed-price proposal within two business days.